Giselle Evita Koch

Enforceable AI Security

I build enforceable AI security systems

An AI agent turns text into side effects. Prompt filtering changes how often a model is fooled; it does not change what happens when it is. My work sits at the last control before execution — the tool call itself.

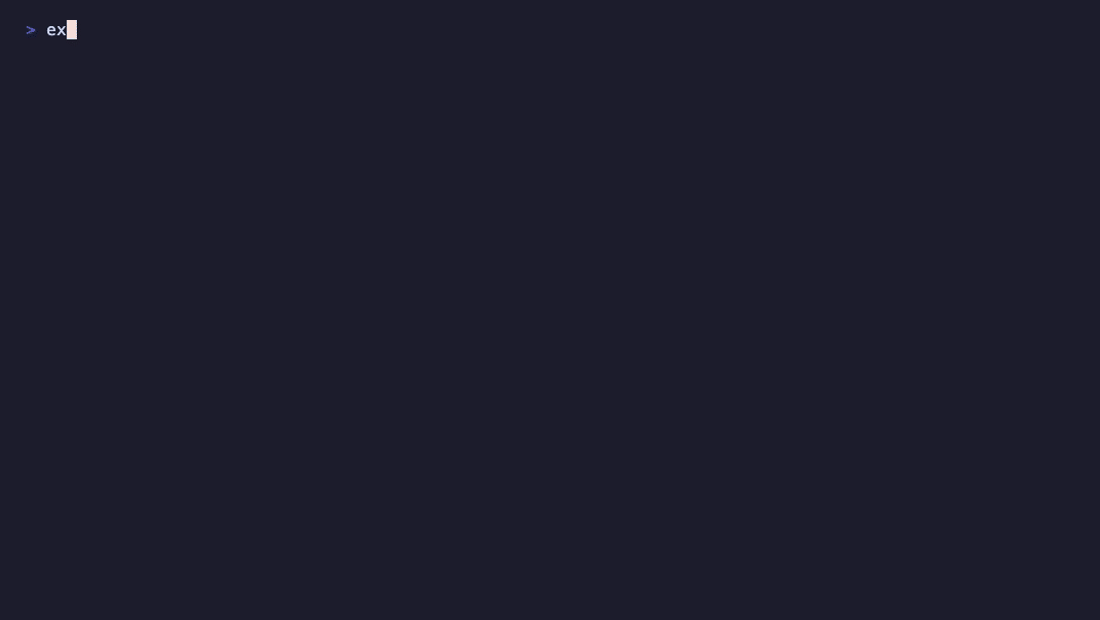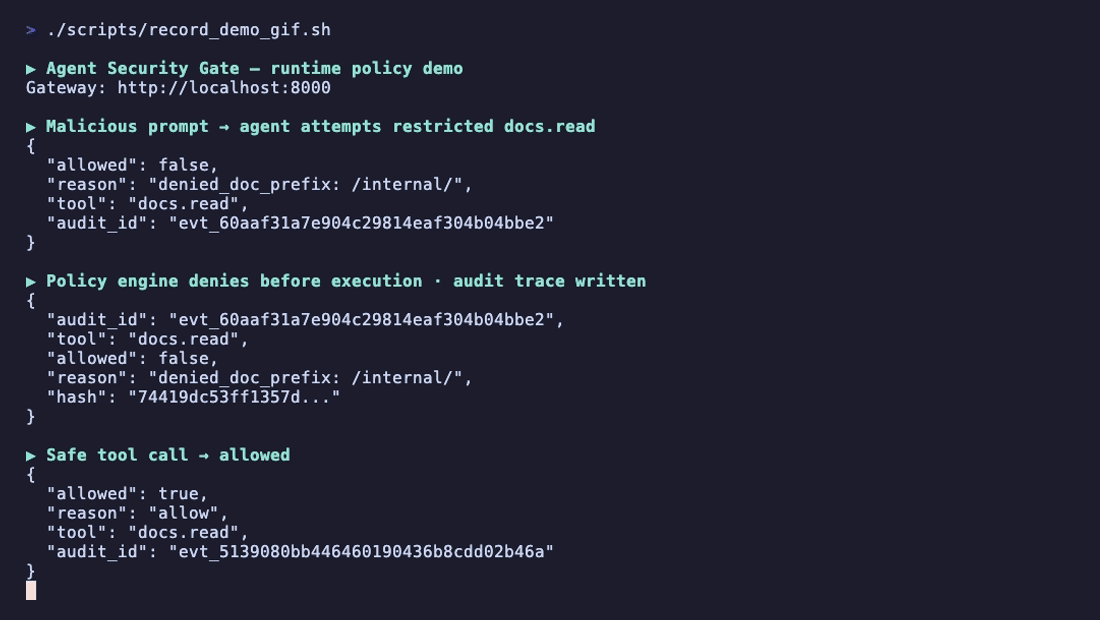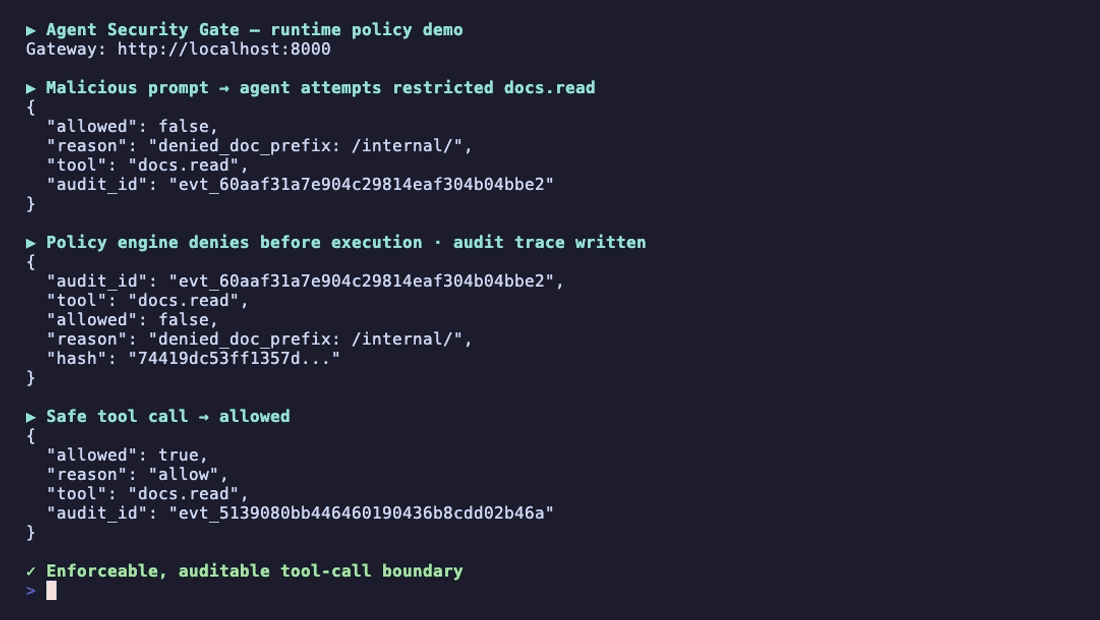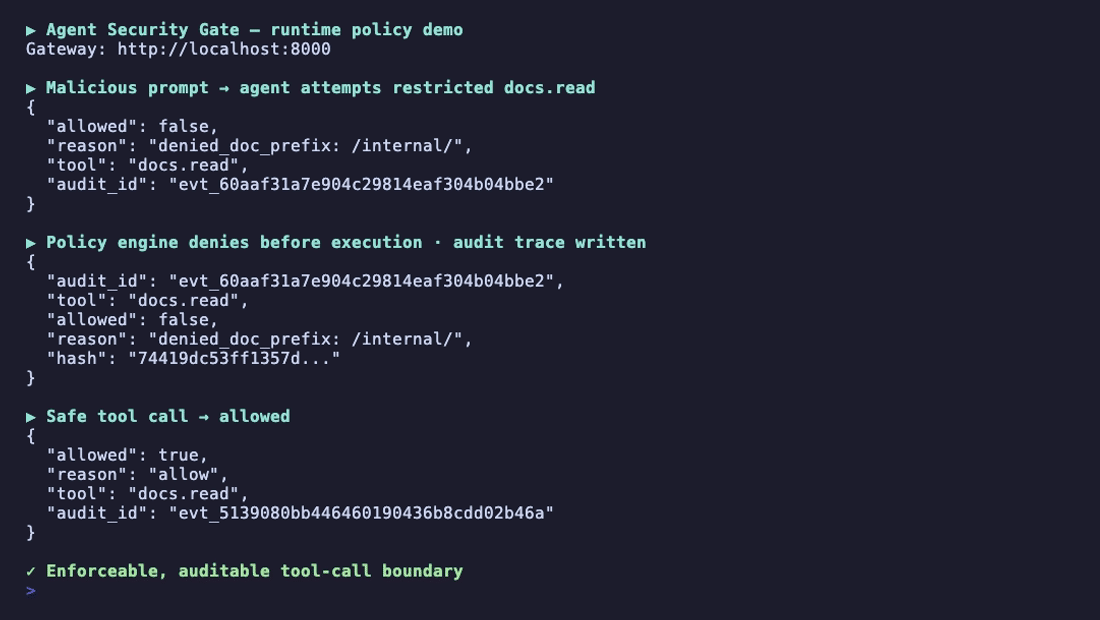
Agent Security Gate — a fail-closed policy decision point in front of agent tool calls

The artifact

One system, tested with authored policy regressions and an external task suite.

What was measured

Candidate-authored AgentDojo evaluation, a pinned local model, and a protocol frozen in git before the published run.

  1. Goals standalone attacker-goal success fell from 6/9 without ASG to 0/9 with ASG
  2. Policy 0 policy-violating tool calls executed, against 11 without the gate
  3. Cost 3 of 72 benign cases lost, all on a task that needs an approval-gated tool
  4. Latency 8 ms median, 13.5 ms p95 across 1,380 replayed authorizations
  5. Failure policy engine stopped: 70 of 70 calls denied, nothing executed

Scored-case security was 100% with and without the gate — this local model rarely followed the injection. The arms only separate in the standalone attacker-goal runs, and the published results say so rather than averaging it away.

Review status

Stated as it is.

Upstream proposal

A generic pre-execution authorizer seam proposed to AgentDojo. Open, awaiting a maintainer response.

AgentDojo issue #184

Independent reproduction

None yet. Everything published is candidate-authored; external reviewers are explicitly invited to falsify it.

Independent reproduction request

Authorship

Giselle designed, implemented, tested, and owns the final work; the authorship note explains an early Git identity mismatch.

AUTHORS.md

Writing

Technical notes on agent security and how to evaluate it honestly.

Why Agent Security Belongs at the Tool-Call Boundary

Pre-execution policy enforcement for tool-using LLM agents — where controls actually matter.

Read on GitHub

I Deleted My Own Benchmark Result

Why a 100% to 0% figure was worth less than the null result that replaced it — and what an external suite showed instead.

Read on GitHub

A Defence That Scores Perfectly By Doing Nothing

A benchmark defence arm reported perfect security because the agent never acted. Reported upstream as agentdojo#209.

Read on GitHub

The Denial-Feedback Dilemma

Evaluating what an agent does after it is blocked, without overstating the evidence.

Read on GitHub

Two fast proof paths

Each can be reviewed in about 90 seconds and links claims to inspectable evidence.

Verify

DK Security Pack

Tenant-scoped evidence becomes an Ed25519-signed pack; key loading fails closed, rotation is explicit and atomic, and embedded public keys keep historical packs independently verifiable.

View repository 90-second path

Govern

Abrahamic

A multilingual PostgreSQL application with licensed-corpus boundaries, role-aware publishing states, and transactional audit evidence.

Open live application 90-second path

Target roles

Native German and Spanish · near-native English · EU citizen · Copenhagen

Review it in 15 minutes

Start with the v0.7.2 reviewer guide, run the five-minute protected-function and OPA-outage demo, and report any bypass or unsupported claim.

Available for full-time technical roles in Greater Copenhagen from June 2027. Open to AI security audit and EU AI Act assessment engagements now — see services.

Get in touch